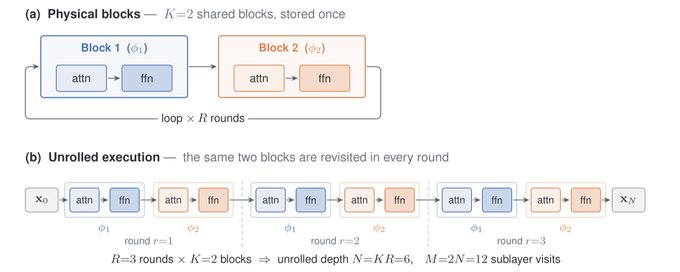
Looped Transformer
- https://x.com/neural_avb/status/2081741935883223196
- https://sebastianraschka.com/llm-architecture-gallery/looped-depth-sharing/
Collected
- https://x.com/neural_avb/status/2081741935883223196
- https://sebastianraschka.com/llm-architecture-gallery/looped-depth-sharing/
A transformer layer can be understood as a key–value memory: a query matches stored keys, then retrieves a weighted blend of their values. The article traces how changing that lookup (outer products, nonlinear MLP activations, softmax attention) reduces interference between memories; in its random-vector estimates, a 64-dimensional key holds roughly 64 memories in a basic linear store, about 2,700 with squared ReLU, and over a million with self-attention. This lens clarifies why these familiar layers differ and how attention’s sharpness helps it select among many context tokens.
Overview of techniques, motivations and considerations in training seven open-weight frontier language models: Hugging Face’s SmolLM3, Prime Intellect’s Intellect 3, Nous Research’s Hermes 4, OpenAI’s gpt-oss-120b, Moonshot’s Kimi K2, DeepSeek’s DeepSeek-R1, and Arcee’s Trinity series.
Navigates through the years, covering the foundational discoveries behind Large Language Models and providing background in a digestible way
The course nagivigates AI agents explaining the theory, design, and implementation